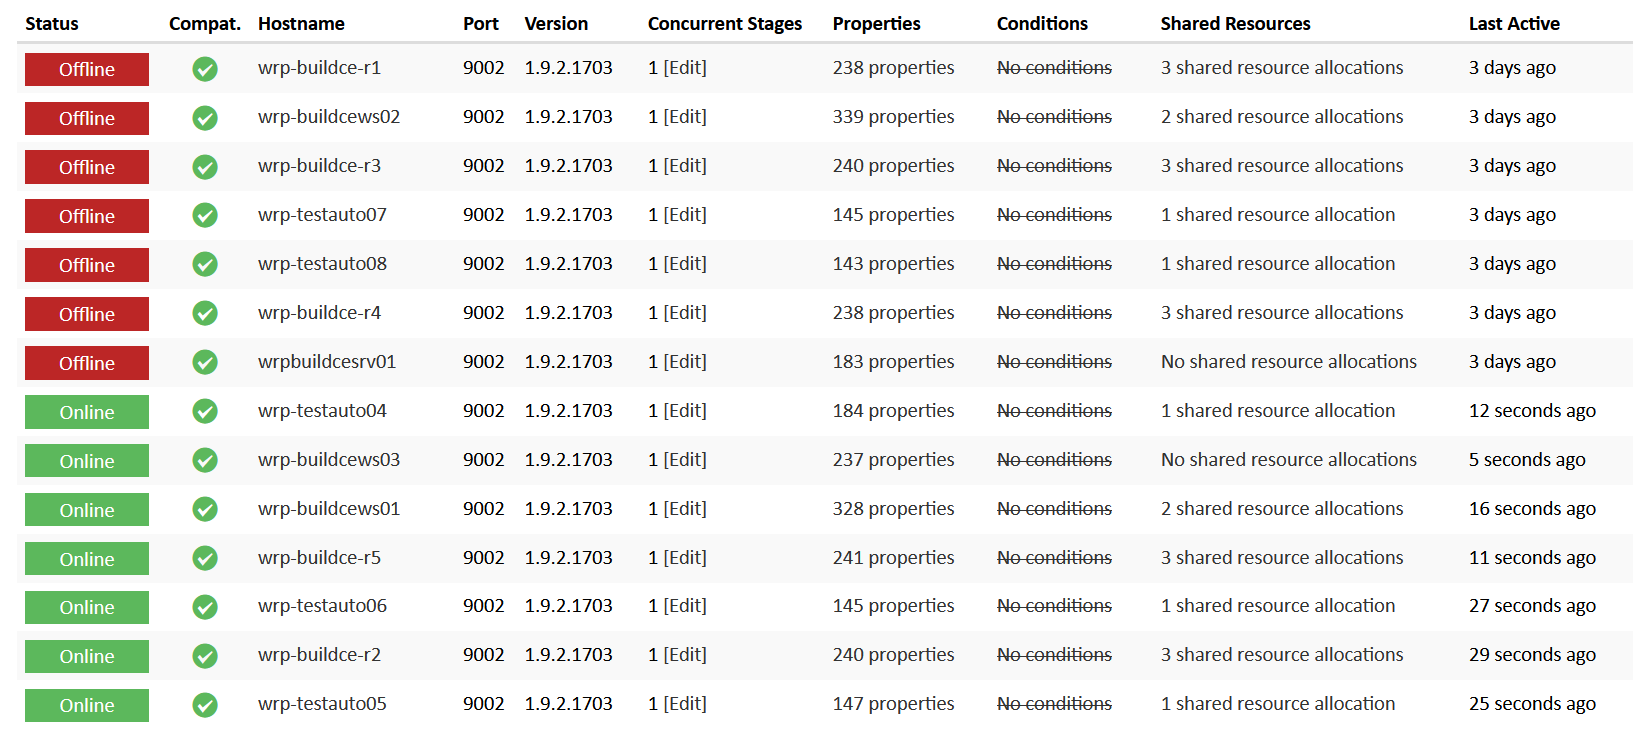
From time to time Continua gets to this strange state that server sees agents as offline, although they are operational, pingable from server/agent and Continua service is running on agent.
Sometimes it’s all agents, sometimes part of agents. Restarting agents does not help, only reboot of server helps.
I suspect the agent registration issues are a side effect of a database connectivity issue.
Looking at the logs, it looks like you are using Postgresql, is that the bundled version or your own postgresql install?
What is the load on the server, cpu usage, memory usage, i/o etc.
You say only rebooting the server works, did you try restarting the ContinuaCIPostgreSQL and ContinuaCI server service and the ContinuaCIPostgreSQL (in that order)?
I used the bundled version of Postgres.
Usually load is not high, but the host resides on backup heavy virtualization and I suspect those problems occur in such moments, but I am not able to verify when each backup runs.
I usually just restart the whole machine as it’s faster for me, but next time I can try to restart only the services.
Yeah virtualization backups can cause problems with i/o - I don’t really have an answer for that. We run our vms on proxmox servers, and backups do not cause us these issues.
We’ll look into this, but I doubt there is going to be a quick fix for it.
I have confirmed that we use builtin proxmox backup and we had a backup done today morning, so this lines up. I am guessing your setup is less stressed and it works, but here this hiccup might be longer and it breaks. Maybe you could add some connection retry mechanism ? Also it’s weird that the problem is with DB but the agents are offline, maybe that is the problem to fix ? Because CI works, builds start, just the agents are falsely offline.
So after me saying we have not had any issues caused by Proxmox backups - guess what happened last night
The problem didn’t happen with a Continua CI machine, but it was on a machine with SQL Server - it was getting major timeouts with the data drive, and in the end the only thing that fixed it was a reboot.
This happened last week too, but I thought it was a windows update problem at the time and didn’t connect the dots.
This seems to be a virtio driver issue - if you google proxmox virtio problems then a lot comes up
Storage and Driver Bugs
Event ID 129 Warnings: Versions of virtio-win between 0.1.215 and 0.1.262 can log vioscsi Event ID 129 (“Reset to device was issued”) in Windows, block I/O, or freeze reboots as outlined in the Proxmox Windows VirtIO Drivers Wiki. [1]
Performance Regressions in Recent Versions: VirtIO driver version 0.1.285 introduces stability and network/SCSI drop bugs for some users; community consensus strongly recommends sticking to or rolling back to stable version 0.1.271. [1, 2]
VirtIO Block vs. VirtIO SCSI: Standard VirtIO block configurations lack native TRIM support and run through limited I/O threading compared to VirtIO SCSI, which can cause performance cliffs or crashes under heavy stress. [1]
The eventlog had lots of those 129 events.
We had virtio 0.1.240 installed - which is in the range of unstable versions - I ended up installing virtio 0.1.271 - we’ll have to wait and see what happens with backups.